Newsletter
Join the Community
Subscribe to our newsletter for the latest news and updates
Public monthly rankings and evidence for AI humanizer performance
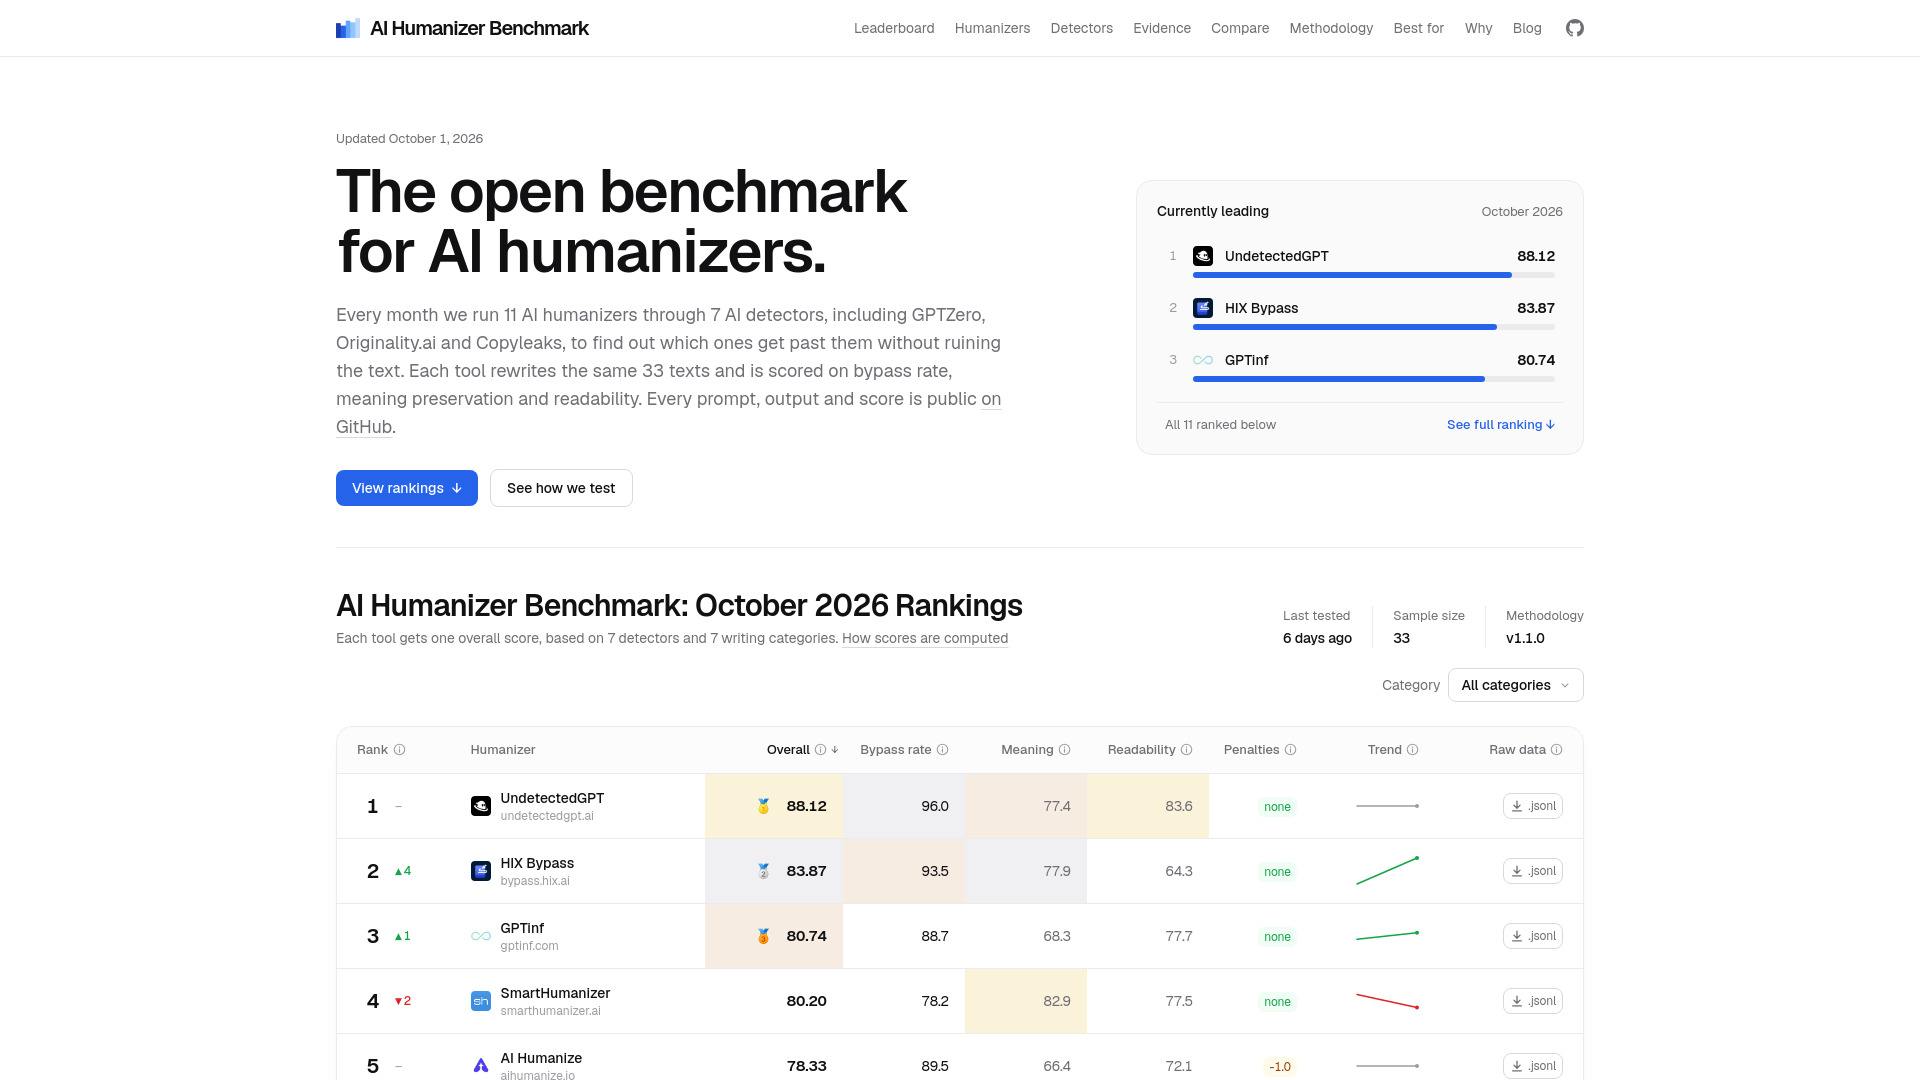
AI Humanizer Benchmark is an independent monthly ranking and evidence platform for AI humanizers. It tests 11 AI humanizers against 7 commercial AI detectors, including GPTZero, Originality.ai, and Copyleaks, to determine which tools can bypass detection without compromising text quality. Each humanizer rewrites the same 33 texts across 7 writing categories and is scored on bypass rate, meaning preservation, readability, and consistency. All raw data, including inputs, outputs, detector verdicts, and scoring code, is publicly available on GitHub.
AI Humanizer Benchmark is a free, independent platform. It does not charge for access to rankings, data, or evidence. The site carries no sponsored content or affiliate links, and vendors cannot pay for positions.
What is an AI humanizer? A tool that rewrites AI-generated text so AI detectors label it as human-written. It changes sentence structure, rhythm, and word choice while trying to keep the meaning the same.
How are the tools tested? Each month, every humanizer rewrites the same set of newly generated texts on its default settings. The texts cover essays, emails, blog posts, and other kinds of writing. Then 7 commercial AI detectors score each rewrite, and every rewrite is also measured for meaning preservation and readability.
What does the score out of 100 mean? It combines four measurements: bypass rate against the detectors (42%), meaning preservation (32%), readability (16%), and consistency across writing types (10%). Penalty points are subtracted for quality problems such as drifting from the original meaning, output that is much longer or shorter than the input, and refusals.
Which AI detectors do you test against? We test against 7 detectors: GPTZero, Originality.ai, Copyleaks, Winston AI, ZeroGPT, QuillBot, and Grammarly.
How often do the rankings change? A new cycle runs each month on newly generated test texts. The draw that picks them stays secret until the cycle closes, so vendors cannot prepare for them. Rankings can shift between cycles. Past cycles stay published and unchanged.
Do tools pay to be listed or ranked? No. The site carries no sponsored content and no affiliate links, and no vendor can pay for a position. A tool's rank depends only on its test results.
UndetectedGPT operates this benchmark. How is bias handled? AI Humanizer Benchmark is run by the team that makes UndetectedGPT, and UndetectedGPT is ranked here. That is a potential conflict of interest, so we publish each monthly cycle in full: inputs, outputs, detector verdicts, scoring rules, and the audit bundle. UndetectedGPT goes through the same pipeline as every other tool.
Can I check the results myself? Yes, in two ways. For a quick check, take any published output, run it through the detector yourself, and compare the verdict with ours. For a full check, clone the public data repository and run one command. It rebuilds the whole leaderboard from the raw inputs, outputs, and detector scores.