What is AI Humanizer Benchmark
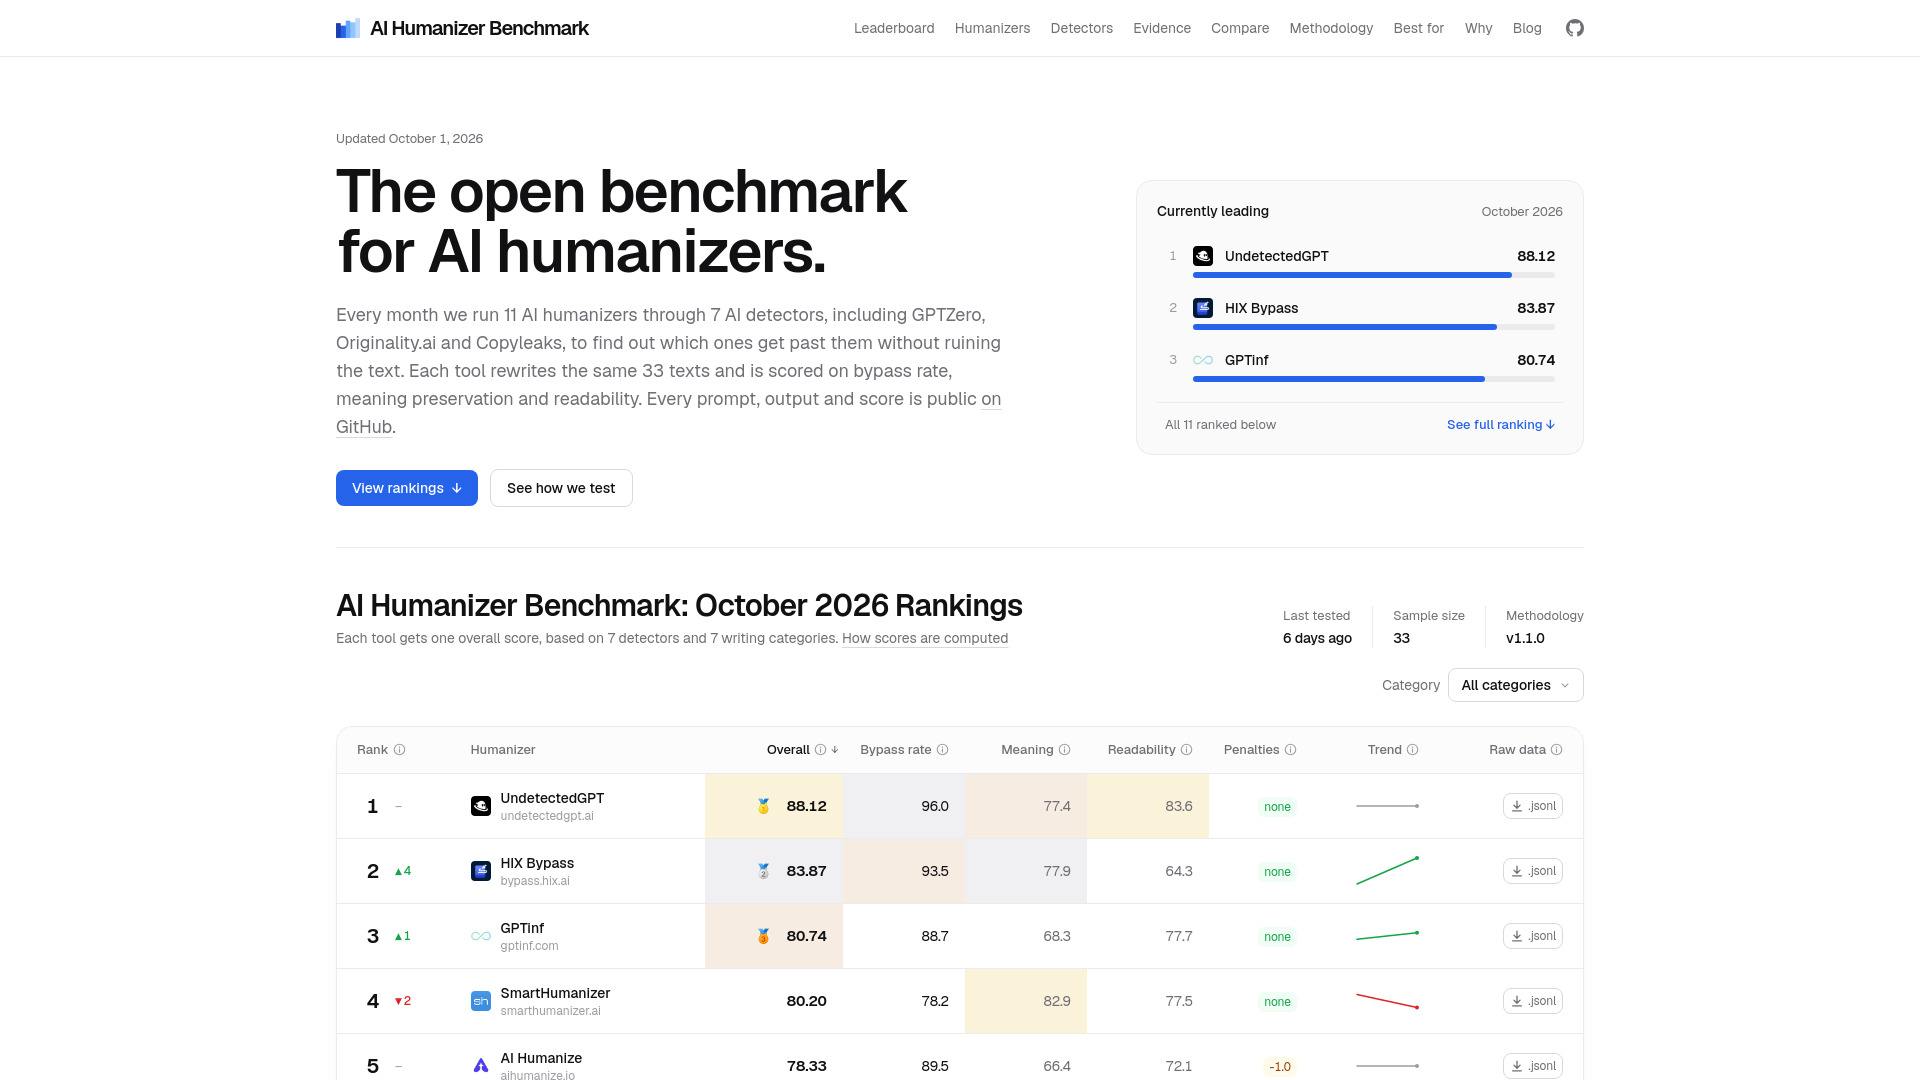
AI Humanizer Benchmark is an independent monthly ranking and evidence platform for AI humanizers. It tests 11 AI humanizers against 7 commercial AI detectors, including GPTZero, Originality.ai, and Copyleaks, to determine which tools can bypass detection without compromising text quality. Each humanizer rewrites the same 33 texts across 7 writing categories and is scored on bypass rate, meaning preservation, readability, and consistency. All raw data, including inputs, outputs, detector verdicts, and scoring code, is publicly available on GitHub.
How to use AI Humanizer Benchmark
- Visit the leaderboard to view the current monthly rankings of AI humanizers.
- Use the category filter to see rankings for specific writing types or use cases.
- Click on any humanizer to see its detailed results, including performance against each detector.
- Explore detector-specific pages to see how humanizers rank against individual detectors like GPTZero or Originality.ai.
- Access the raw data for any humanizer by downloading the JSONL file for the current cycle.
- Review the methodology to understand how scores are computed.
- Check the evidence section to verify results independently.
Features of AI Humanizer Benchmark
- Monthly rankings of 11 AI humanizers based on performance against 7 AI detectors.
- Overall score out of 100, combining bypass rate (42%), meaning preservation (32%), readability (16%), and consistency (10%).
- Penalties for issues like identical output, refusals, meaning drift, and length inflation/deflation.
- Detector panel includes GPTZero, Originality.ai, Copyleaks, Winston AI, ZeroGPT, QuillBot, and Grammarly.
- Raw data for each humanizer available as JSONL files, including inputs, outputs, and detector verdicts.
- Public GitHub repository with all data and scoring code for independent verification.
- Use-case-specific rankings, such as best for students, essays, SEO, academic writing, and more.
- Trend indicators showing rank changes from previous cycles.
- Transparent methodology with detailed scoring formula and penalty breakdown.
Use Cases of AI Humanizer Benchmark
- Students: Find humanizers that perform well on academic essays and can bypass detectors used in education.
- Content creators and SEO professionals: Identify tools that produce human-like content for blog posts and marketing copy.
- Academic writers: Evaluate humanizers for theses, papers, and applications where meaning preservation is critical.
- Businesses: Select humanizers for professional emails, reports, and other business writing.
- Researchers: Use the public data to study AI detection and humanization techniques.
- General users: Compare humanizers based on quality, readability, and bypass rate for personal writing tasks.
Pricing
AI Humanizer Benchmark is a free, independent platform. It does not charge for access to rankings, data, or evidence. The site carries no sponsored content or affiliate links, and vendors cannot pay for positions.
FAQ
What is an AI humanizer? A tool that rewrites AI-generated text so AI detectors label it as human-written. It changes sentence structure, rhythm, and word choice while trying to keep the meaning the same.
How are the tools tested? Each month, every humanizer rewrites the same set of newly generated texts on its default settings. The texts cover essays, emails, blog posts, and other kinds of writing. Then 7 commercial AI detectors score each rewrite, and every rewrite is also measured for meaning preservation and readability.
What does the score out of 100 mean? It combines four measurements: bypass rate against the detectors (42%), meaning preservation (32%), readability (16%), and consistency across writing types (10%). Penalty points are subtracted for quality problems such as drifting from the original meaning, output that is much longer or shorter than the input, and refusals.
Which AI detectors do you test against? We test against 7 detectors: GPTZero, Originality.ai, Copyleaks, Winston AI, ZeroGPT, QuillBot, and Grammarly.
How often do the rankings change? A new cycle runs each month on newly generated test texts. The draw that picks them stays secret until the cycle closes, so vendors cannot prepare for them. Rankings can shift between cycles. Past cycles stay published and unchanged.
Do tools pay to be listed or ranked? No. The site carries no sponsored content and no affiliate links, and no vendor can pay for a position. A tool's rank depends only on its test results.
UndetectedGPT operates this benchmark. How is bias handled? AI Humanizer Benchmark is run by the team that makes UndetectedGPT, and UndetectedGPT is ranked here. That is a potential conflict of interest, so we publish each monthly cycle in full: inputs, outputs, detector verdicts, scoring rules, and the audit bundle. UndetectedGPT goes through the same pipeline as every other tool.
Can I check the results myself? Yes, in two ways. For a quick check, take any published output, run it through the detector yourself, and compare the verdict with ours. For a full check, clone the public data repository and run one command. It rebuilds the whole leaderboard from the raw inputs, outputs, and detector scores.