Newsletter
Join the Community
Subscribe to our newsletter for the latest news and updates
Open-source data platform combining pipelines, quality checks, lineage, and AI analytics.
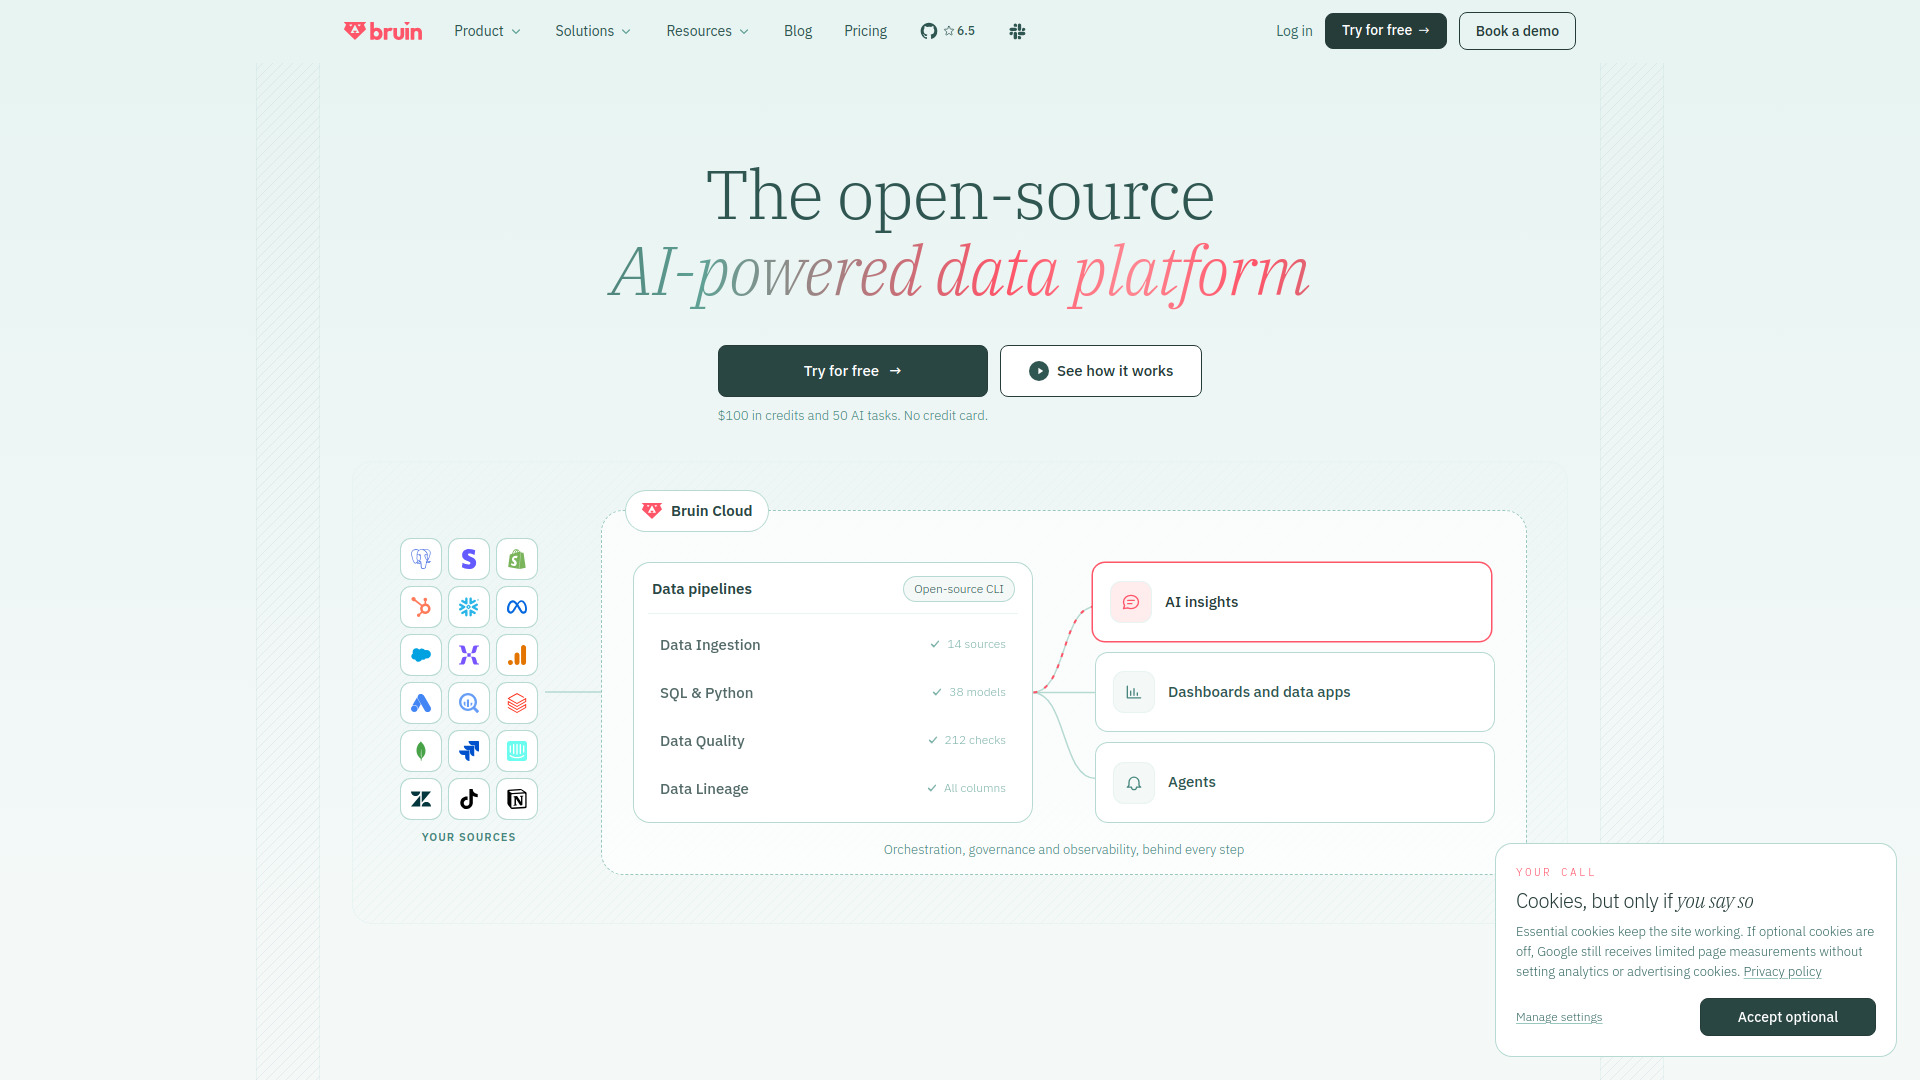
Bruin is an open-source, AI-powered data platform that combines data ingestion, SQL and Python pipelines, quality checks, column-level lineage, and an AI data analyst. It replaces the typical Fivetran + dbt + Airflow + BI + ChatGPT-on-data stack with one platform. The core CLI is Apache 2.0-licensed and self-hostable, with an optional managed cloud that adds AI capabilities, governance, and scheduling.
assets/raw/orders.asset.yml) specifying source connections, destination, incremental strategies, and column-level checks.assets/marts/revenue_daily.sql).bruin run command, which executes ingestion, transformation, and quality checks in order.What is Bruin?
Bruin is an end-to-end AI data platform that combines data ingestion, SQL and Python pipelines, automated quality checks, column-level lineage, and an AI data analyst that lives in Slack, Microsoft Teams, Google Chat, WhatsApp, Discord, Telegram, email, and Bruin Cloud. It replaces the typical Fivetran + dbt + Airflow + BI + ChatGPT-on-data stack.
Where can I use Bruin?
Anywhere your team already works: Slack, Microsoft Teams, Google Chat, WhatsApp, Discord, Telegram, email, and the browser (Bruin Cloud).
How is Bruin different from dbt?
dbt only handles SQL transformation. Bruin handles ingestion, transformation in both SQL and Python, orchestration, quality checks, column-level lineage, and an AI analyst on top—all in one platform with a Git-native CLI.
Does Bruin replace Fivetran?
Yes. Bruin has built-in connectors covering APIs, databases, data warehouses, SaaS apps, cloud storage, webhooks, and event streams, with new sources added continuously.
Is Bruin an Airflow alternative?
Yes. Bruin runs SQL and Python pipelines on a Git-native schedule with no separate orchestrator to host, scale, or maintain. It also handles ingestion, quality checks, lineage, and an AI analyst.
Does Bruin work with Snowflake, BigQuery, and Databricks?
Yes, natively. Bruin connects to all major data warehouses and runs transformations directly inside them, so your data never leaves your infrastructure.
Does Bruin have an AI data analyst?
Yes. Ask questions in plain English in any supported channel. Bruin answers using your live pipelines, metadata, and quality state, ensuring consistent answers across the organization.
Is Bruin open source?
Yes. The Bruin CLI core is Apache 2.0-licensed and self-hostable. A managed cloud platform layer adds the AI analyst, AI dashboards, governance, scheduling, and team access controls.
How fast can teams get started with Bruin?
Minutes to first pipeline using the open-source CLI. Under two minutes to first dashboard from a chat prompt on the managed platform.
Is Bruin SOC 2 and ISO 27001 compliant, and enterprise-ready?
Yes. Bruin is ISO/IEC 27001:2022 certified and SOC 2 Type 2 attested, supports role-based access control, audit logs, VPC peering, and region selection. Transformations run inside your warehouse, so customer data never leaves your infrastructure.
Can I self-host Bruin?
Yes. The Bruin CLI is Apache 2.0-licensed and runs anywhere you can run a binary, including on-prem and air-gapped environments.
How does Bruin handle data privacy with the AI analyst?
Your raw data is never used to train any model. The AI analyst reads schema, metadata, and quality state, generates SQL, and runs that SQL against your warehouse. Only the results needed to answer the question pass through, and all model calls go through enterprise LLM endpoints with no-training agreements.
Does Bruin support Python pipelines, not just SQL?
Yes. SQL and Python are first-class citizens. Write Python assets for machine learning feature engineering, custom ingestion logic, or anything SQL cannot express.
Do I have to use all of Bruin, or can I mix it with my existing tools?
Each layer is independent, so you can adopt as much or as little of Bruin as you want. Keep Fivetran or Airbyte for ingestion and use only Bruin's transformation layer, run dbt models side by side, or point the AI analyst at an existing warehouse.
Does Bruin work with my existing dbt, Airflow, or LookML repos?
Yes. Bruin reads your existing pipelines and semantic layers directly: dbt models and tests, Airflow DAGs, LookML, Dagster and Prefect jobs, and custom pipelines. It builds a semantic understanding on top of what's already there.
Does Bruin lock you in?
No. Your pipelines are plain SQL, Python, and YAML files in your own Git repository, your data stays in your own warehouse, and the Bruin CLI is open source under Apache 2.0. Bruin Cloud is optional.
Who uses Bruin?
Data teams at companies including Lessmore, StarBerry, NativeMinds, SCG, ProphetX, Buluttan, Spektra Games, Workhy, M8 Games, and Fabrikatör. Published results include 88% lower warehouse cost, 3x faster pipelines than a dbt setup, 90% fewer data failures, and one person running an entire data and analytics function.
How hard is it to migrate from an existing data stack?
Incremental, not a rewrite. bruin import database turns existing warehouse tables into Bruin assets in one command, dbt models port with their Jinja intact, the Fivetran migration template maps each connector to an ingestr load with an approval step, and you can run Bruin from an existing Airflow DAG while you move.