What is Datalab.to
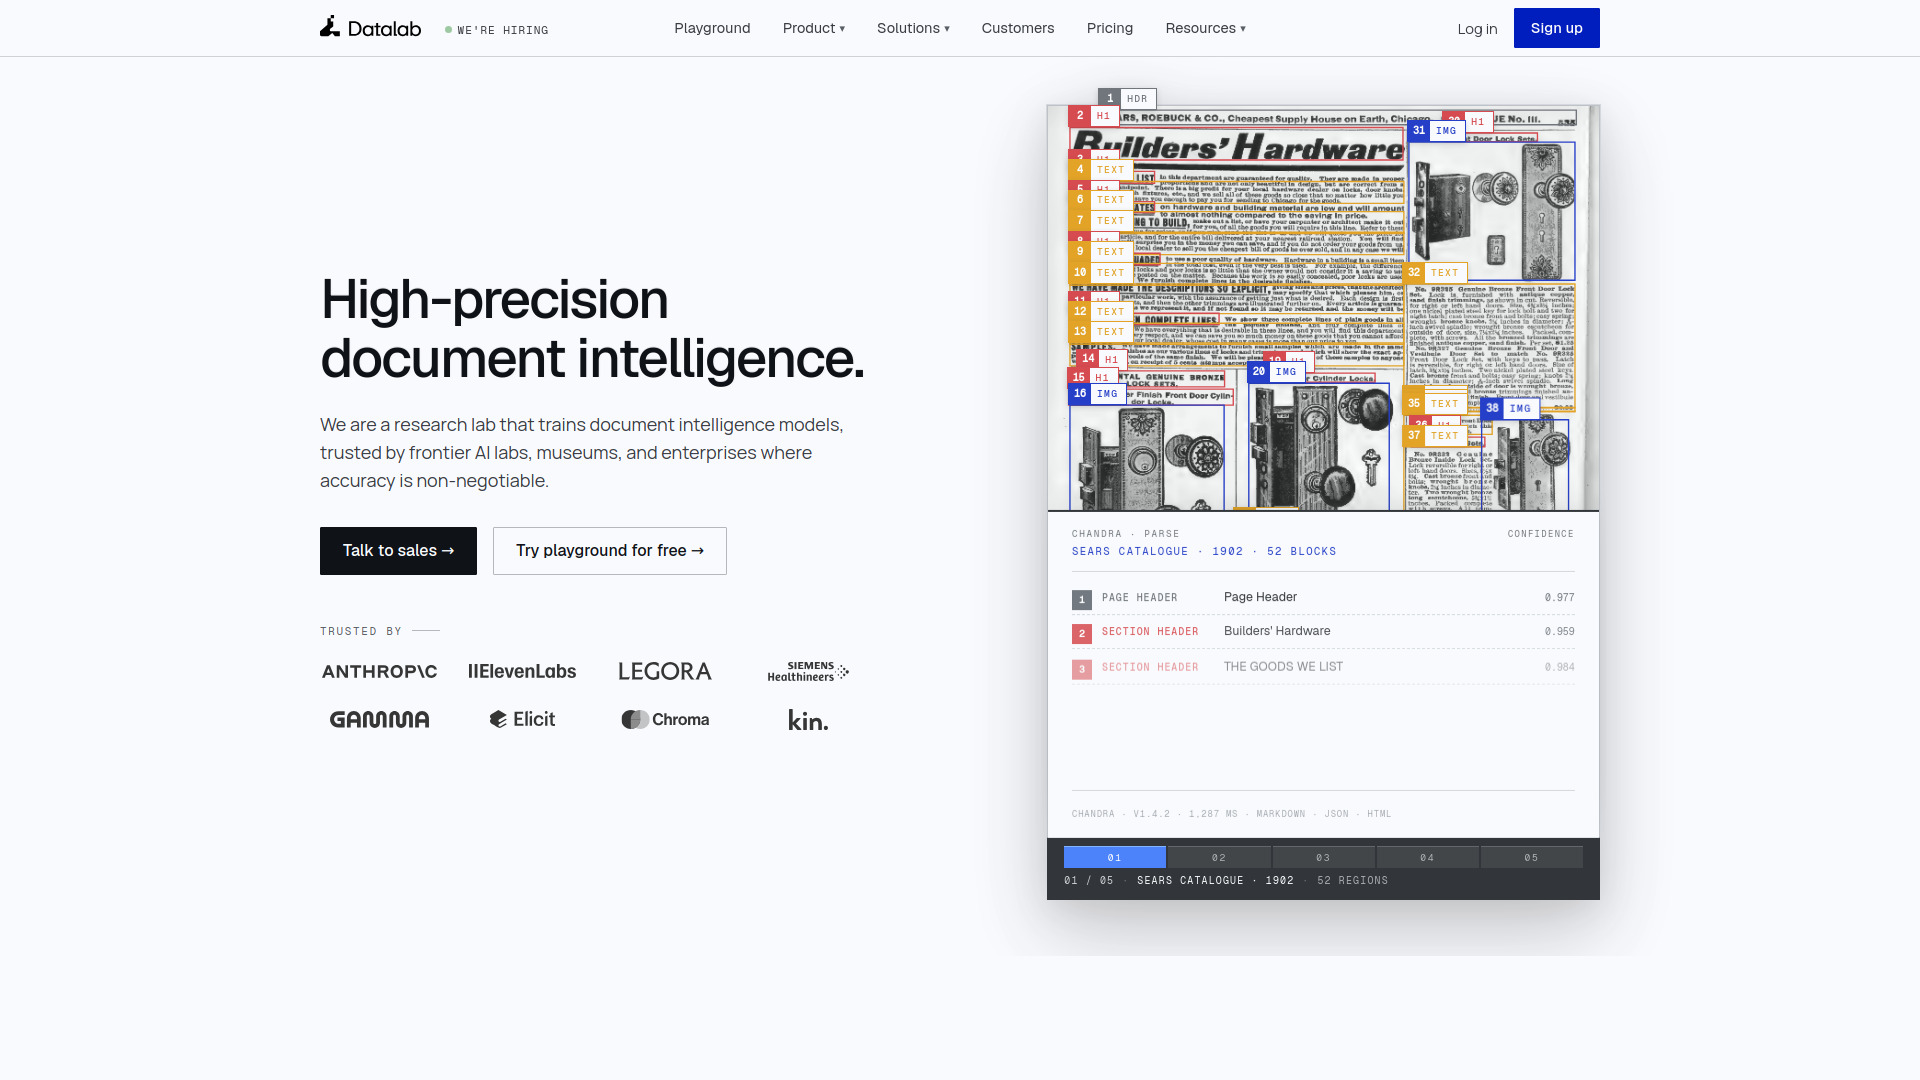
Datalab.to is a document intelligence platform that transforms unstructured content into precise, production-ready data. It is developed by a research lab that trains document intelligence models, trusted by frontier AI labs, museums, and enterprises where accuracy is non-negotiable. The platform equips organizations to feed AI systems and automate workflows with dependable, audit-ready data.
How to use Datalab.to
- Sign up or log in: Create an account or log in to access the platform.
- Choose a processor: Select from available processors such as Convert, Extract, Segment, or Eval.
- Compose a pipeline: Use the playground to wire processors into a pipeline. Pick the processors you need and compose them in the playground.
- Promote to production: Once satisfied, promote a versioned pipeline to production.
- Deploy: Run models in managed cloud, in your VPC, or fully air-gapped.
- Monitor: Continuously evaluate quality against rubrics and a reference corpus; regressions are flagged.
Features of Datalab.to
- Processors:
- Convert: Use Chandra to convert PDFs, spreadsheets, slides and more to structured markdown, HTML, and JSON. Includes word-level bounding boxes, redlines, and more.
- Extract: Find key information using pre-defined extraction schemas.
- Segment: Identify natural boundaries between documents that were originally combined into one file.
- Eval: Evaluate the quality of output, using our criteria or your own rubrics for quality.
- Pipeline composition: Wire processors into a pipeline, compose in the playground, and promote versioned pipelines to production.
- Deployment options: Managed cloud, in your VPC, or fully air-gapped. You choose the network.
- Monitoring: Continuous evals against rubrics and a reference corpus; quality improves with model updates, and regressions are flagged.
- Benchmarks: Best-in-class performance on public datasets such as olmOCR-bench for tables, multilingual, math, and arXiv.
- Output formats: Markdown, JSON, HTML.
- Bounding boxes: Word-level bounding boxes for precise parsing.
Use Cases of Datalab.to
- AI Research Labs: Parse and extract data from research papers, such as 'Attention Is All You Need' from arXiv.
- AI x Science: Process scientific documents and diagrams.
- Financial Services: Extract data from financial documents like 10-K filings (e.g., Berkshire Hathaway 10-K).
- Healthcare: Parse clinical trial documents and medical records.
- Insurance: Process claims forms and policy documents.
- Museums and Enterprises: Digitize historical documents like the Sears Catalogue from 1902 and the Wright Patent from 1906.
- General: Transform unstructured content into production-ready data for AI systems and workflow automation.
Pricing
Pricing information is not detailed on this page. For pricing details, please refer to the pricing page.
FAQ
What is Datalab.to?
Datalab.to is a document intelligence platform that transforms unstructured content into precise, production-ready data.
Who uses Datalab.to?
It is trusted by frontier AI labs, museums, and enterprises where accuracy is non-negotiable.
What processors are available?
Convert, Extract, Segment, and Eval.
Can I try Datalab.to for free?
Yes, you can try the playground for free.
How accurate is Datalab.to?
It achieves best-in-class performance on benchmarks such as olmOCR-bench, with scores like 90.7% for tables, 80.4% for multilingual, 90.2% for math, and 90.4% for arXiv.
What deployment options are available?
Managed cloud, in your VPC, or fully air-gapped.
What output formats are supported?
Markdown, JSON, and HTML.