What is Doubleword
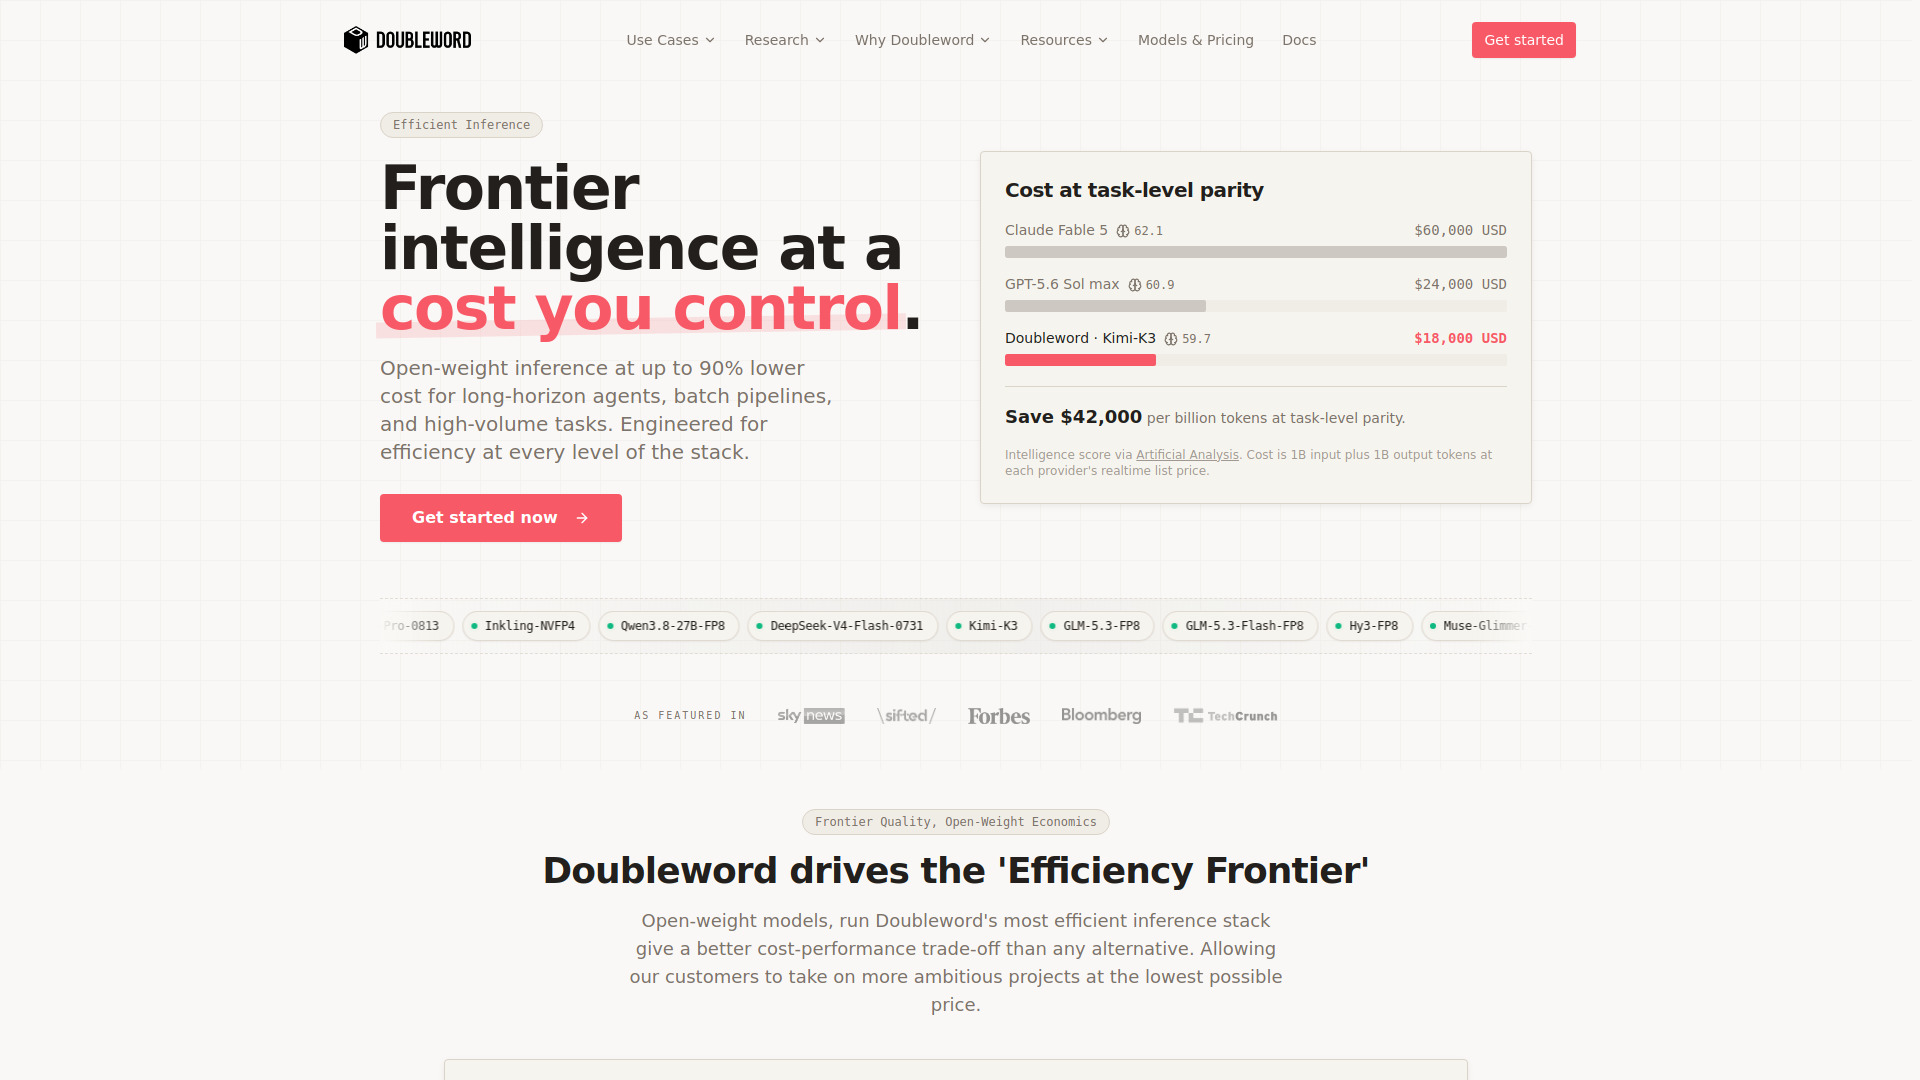
Doubleword is a low-cost, scalable inference platform for high-volume AI workloads. It runs open-weight models on its own GPUs, offering async and batch inference up to 90% cheaper than real-time APIs. It is OpenAI-compatible and designed for agents, evals, and pipelines.
How to use Doubleword
- Sign up and create an API key in the Console.
- Choose a model from the catalog.
- Point the OpenAI SDK at
https://api.doubleword.ai/v1and send a request. - For lower-cost async inference, add
service_tier: "flex". - For batch jobs, use the
/batchendpoint with a JSONL file, upload via dashboard, CLI, or Autobatcher.
Features of Doubleword
- Cost efficiency: Up to 90% cheaper than closed-source APIs, with batch cheaper than async and async cheaper than realtime.
- Open-weight models: Supports leading open-source models like DeepSeek, GLM, Kimi, Qwen, and more.
- OpenAI and Anthropic compatible: Migrate with a simple base URL change.
- Multiple latency tiers: Realtime, async (1-minute start SLA), and batch (24-hour SLA).
- High throughput: Optimized for high-volume workloads with efficient GPU utilization.
- Prompt caching: Can cut input costs by up to ~90% with high cache hit rates.
- Region-specific routing: Choose between Europe and US deployments.
- Partial batch results: Download completed results while a batch is still running.
- Security: No training on data by default, opt-in Zero Data Retention, SOC 2 status.
Use Cases of Doubleword
- AI agents: Long-running, multi-turn agents with tool calling and structured outputs.
- Batch pipelines: High-volume ETL, extraction, and data processing.
- Evals: Running evaluations at scale.
- Coding and maths workflows: Models like Qwen3.8-27B.
- Multimodal agentic coding: GLM-5.3-Flash.
- High-throughput tasks: DeepSeek-V4-Flash for extraction.
Pricing
Doubleword uses simple pay-per-token pricing with prepaid credits and no minimum. Prices drop with latency flexibility: batch is cheaper than async, and async is cheaper than realtime. For example, Kimi-K3 costs $11.25 per 1M output tokens async and $7.50 batch. GLM-5.3-Flash costs $0.38 async and $0.25 batch. Prompt caching can reduce input costs further.
FAQ
How do I get started? Sign up, create an API key, choose a model, and point the OpenAI SDK at the API endpoint.
Is Doubleword a router? No. Doubleword owns and runs the GPUs, ensuring consistent model builds and pricing.
Which models are supported? Leading open-source models including DeepSeek, GLM, Kimi, Qwen, and more.
Are open-source models reliable? Yes, they show task-level parity with closed-source APIs on intelligence indices.
What are the rate limits? New accounts have initial limits; adding a payment method lifts them. Async tier offers higher limits.
Can I download partial batch results? Yes, you can download completed results while a batch is running.
What happens if a batch fails? Doubleword retries and recovers automatically, saving partial results.
Is data secure? Data is encrypted in transit and at rest, with opt-in Zero Data Retention and no training on data by default.